<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en-US"><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://luispe.me/feed.xml" rel="self" type="application/atom+xml" /><link href="https://luispe.me/" rel="alternate" type="text/html" hreflang="en-US" /><updated>2026-08-30T04:53:16+00:00</updated><id>https://luispe.me/feed.xml</id><title type="html">Luis P. Perez</title><subtitle>Luis P. Perez is a technical product leader with experience building risk decisioning, compliance technology, ML-powered products, and foundational data products, now extending that background into GenAI and context engineering.</subtitle><author><name>Luis P. Perez</name></author><entry><title type="html">The Stop That Could Never Fire</title><link href="https://luispe.me/2026/08/18/the-stop-that-could-never-fire.html" rel="alternate" type="text/html" title="The Stop That Could Never Fire" /><published>2026-08-18T00:00:00+00:00</published><updated>2026-08-18T00:00:00+00:00</updated><id>https://luispe.me/2026/08/18/the-stop-that-could-never-fire</id><content type="html" xml:base="https://luispe.me/2026/08/18/the-stop-that-could-never-fire.html"><![CDATA[<p>My 0DTE bot opened a position late enough that its configured time stop landed after the market close.</p>

<p>At the bell, the main loop did exactly what it was designed to do: it ended the session. The resting profit-taking order remained open, the time stop never had a chance to fire, and the option expired worthless.</p>

<p>No single component was obviously broken.</p>

<h2 id="the-bug-lived-between-correct-components">The bug lived between correct components</h2>

<p>The time stop was calculated correctly from the fill. The session loop stopped correctly at the market close. The exit order was placed correctly and waited for a price the market never reached.</p>

<p>The failure existed in the composition:</p>

<ul>
  <li>the deadline code did not know when the process would stop listening</li>
  <li>the session-close code did not know a position still needed management</li>
  <li>the summary counted only journaled closes, so it omitted the abandoned trade</li>
</ul>

<p>This is the kind of incident unit tests can miss when each function’s local contract is correct. The system-level contract—never end while a position may still be open—was not encoded.</p>

<h2 id="reuse-the-safety-behavior-already-present">Reuse the safety behavior already present</h2>

<p>The frustrating part was that the bot already knew how to handle this condition.</p>

<p>Its emergency-halt path checked for an active position, attempted to flatten it, refused to end until the close was confirmed, and raised an urgent alert when confirmation failed. That reviewed behavior sat near an unconditional session-close branch that simply called <code class="language-plaintext highlighter-rouge">break</code>.</p>

<p>The fix reused the existing close primitive instead of adding another order path. Session end and emergency halt now share the same invariant: do not declare the session finished while the broker may still hold the position.</p>

<h2 id="derive-the-entry-cutoff">Derive the entry cutoff</h2>

<p>A fixed “no new trades after this clock time” rule would solve only the current configuration. Different hold periods need different cutoffs, and shortened sessions move the close.</p>

<p>The entry gate is derived instead:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>session_exit_deadline = market_close - operational_buffer

accept entry only if:
expected_fill_time + configured_hold_period &lt;= session_exit_deadline
</code></pre></div></div>

<p>The gate uses the expected fill, not the signal timestamp. A completed signal bar can lag wall-clock time, and a submitted order can take time to confirm. The exit timer begins from the fill, so the admission decision must reason about that same clock.</p>

<p>The calculation also uses the session calendar, which means the cutoff moves automatically on early-close days.</p>

<h2 id="prevention-and-containment-are-different">Prevention and containment are different</h2>

<p>The entry gate prevents this specific late trade. It does not cover every way a position can become stranded.</p>

<p>A separate authentication incident had already produced the same dangerous state through a different path. That changed the scope of the fix:</p>

<ul>
  <li>the derived gate prevents an exit deadline beyond the session</li>
  <li>an end-of-session sweep contains any open position, regardless of cause</li>
  <li>failure to confirm the sweep keeps the recovery path alive and the alerts active</li>
</ul>

<p>The clever rule handles one cause. The boring sweep handles the category.</p>

<p>An independent review found that my first retry still had a hole: it returned early while the time stop was in the future, which was precisely the original scenario. A second review corrected my explanation of broker behavior and exposed the real issue—the fallback close could not proceed until the resting exit was cancelled.</p>

<p>The check I am keeping is simple: whenever code computes a deadline, ask whether the program will still be alive to observe it.</p>

<p>Timers assume someone is around to hear them. Mine was not.</p>

<p><em>This incident review is educational and is not investment advice.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="incident-review" /><category term="reliability" /><summary type="html"><![CDATA[Three correct components still abandoned a late-session option position because its exit deadline landed after the trading loop ended for the day.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">The Bot That Walked Away</title><link href="https://luispe.me/2026/08/17/the-bot-that-walked-away.html" rel="alternate" type="text/html" title="The Bot That Walked Away" /><published>2026-08-17T00:00:00+00:00</published><updated>2026-08-17T00:00:00+00:00</updated><id>https://luispe.me/2026/08/17/the-bot-that-walked-away</id><content type="html" xml:base="https://luispe.me/2026/08/17/the-bot-that-walked-away.html"><![CDATA[<p>My 0DTE bot submitted an entry, spent about a minute failing to confirm the fill, logged <code class="language-plaintext highlighter-rouge">Aborting</code>, and went back to scanning for signals.</p>

<p>The order had filled. The bot was no longer managing the position. No time-based exit, no profit target, no recovery loop. The option later expired worthless.</p>

<p>My first theory was wrong in a useful way.</p>

<h2 id="the-retry-existed-but-the-error-never-reached-it">The retry existed, but the error never reached it</h2>

<p>I suspected that entry confirmation was missing the authentication recovery used elsewhere in the bot.</p>

<p>The polling loop did call the retry wrapper. One layer below it, however, the broker method caught every exception and returned a polite <code class="language-plaintext highlighter-rouge">success=False</code> object. The underlying <code class="language-plaintext highlighter-rouge">401 Unauthorized</code> never propagated to the code designed to refresh credentials.</p>

<p>The retry wrapper was not bypassed. It was starved.</p>

<p>The polling loop then discarded the error detail it did receive. The logs repeated “failed to fetch order” while the actual status code sat unused in the response object.</p>

<p>This is the danger of broad exception handling in a lower layer: it can make a function look resilient while disabling the recovery policy above it.</p>

<h2 id="shared-authentication-made-failures-routine">Shared authentication made failures routine</h2>

<p>Multiple bot processes shared token state. When one process refreshed, another could keep an older access token in memory while its local expiry timestamp still looked valid.</p>

<p>The next broker call would fail, trigger another refresh, and rotate the token again. The logs showed a cascade across processes.</p>

<p>Instead of assuming those bursts could be eliminated immediately, I changed the system to survive them.</p>

<h2 id="unknown-is-a-position-state">Unknown is a position state</h2>

<p>The entry path now distinguishes three outcomes:</p>

<ul>
  <li><strong>filled</strong> — adopt and manage the position</li>
  <li><strong>dead</strong> — confirmed cancelled or rejected with no fill</li>
  <li><strong>unknown</strong> — neither state is proved</li>
</ul>

<p>Unknown no longer means abort. The bot recovers authentication, checks the order again, cancels any remaining open quantity, and queries the broker’s actual positions.</p>

<p>If the contract is held, the bot adopts the broker quantity and begins normal exit management. If state is still ambiguous, it keeps reconciling and alerting through the session instead of returning to signal scanning.</p>

<p>Authentication recovery also moved to the broker layer, where every request passes through one policy. On a <code class="language-plaintext highlighter-rouge">401</code>, a process first adopts the newer token already written by a sibling. It creates a new token only if adoption fails.</p>

<h2 id="review-the-fix-in-a-different-mental-model">Review the fix in a different mental model</h2>

<p>The sharpest review finding was a partial fill. My first “dead order” branch treated a cancelled order as flat without checking whether some quantity had filled before cancellation.</p>

<p>The review also caught two related mistakes:</p>

<ul>
  <li>adopted size came from configuration instead of the position actually held</li>
  <li>stacked retry layers multiplied the refresh behavior I was trying to contain</li>
</ul>

<p>Those bugs were inside the recovery code because I was still thinking in the all-filled-or-not-filled shape of the original incident.</p>

<p>As an independent tripwire, the bot now periodically compares its tracked positions with the broker’s positions and alerts on drift. It is intentionally alert-only. Reconciliation detects disagreement; it does not improvise a trade.</p>

<h2 id="the-operational-lesson">The operational lesson</h2>

<p>An urgent notification is not risk management. I received the original alert and read it too late. Anything the system must do—such as continue managing a possibly live position—belongs in the system’s recovery behavior, not in a request for a human to notice.</p>

<p>The absence of fill confirmation is not evidence that no fill occurred. When the order state is unclear, ask the broker what the account actually owns and keep watching until the ambiguity is resolved.</p>

<p><em>This incident review is educational and is not investment advice.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="incident-review" /><category term="reliability" /><summary type="html"><![CDATA[A filled order went unmanaged after authentication failed. The fix was to treat unknown order state as risk, recover it safely, and keep watching.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">A Kill Switch That Doesn’t Abandon the Trade</title><link href="https://luispe.me/2026/07/16/remote-kill-switch-for-an-autonomous-trading-bot.html" rel="alternate" type="text/html" title="A Kill Switch That Doesn’t Abandon the Trade" /><published>2026-07-16T00:00:00+00:00</published><updated>2026-07-16T00:00:00+00:00</updated><id>https://luispe.me/2026/07/16/remote-kill-switch-for-an-autonomous-trading-bot</id><content type="html" xml:base="https://luispe.me/2026/07/16/remote-kill-switch-for-an-autonomous-trading-bot.html"><![CDATA[<p>An autonomous trading bot is convenient until I decide, mid-session and away from my computer, that it should stop.</p>

<p>The obvious controls are unsafe or ineffective. Changing an environment variable does not mutate the environment of a running process. Killing the process can orphan an open position with no code left to manage its exit.</p>

<p>The requirement was sharper: a running bot needed to observe a remote instruction, stop taking risk, and never abandon a position.</p>

<h2 id="poll-a-control-the-process-can-see">Poll a control the process can see</h2>

<p>The bot already has a loop, so each iteration can read external state. The first version used a local sentinel file:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">is_trading_halted</span><span class="p">(</span><span class="o">*</span><span class="n">scopes</span><span class="p">):</span>
    <span class="k">if</span> <span class="n">halt_file_exists</span><span class="p">():</span>
        <span class="k">return</span> <span class="bp">True</span>
    <span class="k">return</span> <span class="nb">any</span><span class="p">(</span><span class="n">scoped_halt_exists</span><span class="p">(</span><span class="n">scope</span><span class="p">)</span> <span class="k">for</span> <span class="n">scope</span> <span class="ow">in</span> <span class="n">scopes</span> <span class="k">if</span> <span class="n">scope</span><span class="p">)</span>
</code></pre></div></div>

<p>The local file has one excellent property: it works without a network. It is the offline emergency brake. Its weakness is reachability—I still need shell access to create it.</p>

<p>For remote control, I added small JSON policy documents in S3. The bot makes outbound reads; my phone can update the document through a separately permissioned path. The trading machine does not expose a new web server or inbound port.</p>

<h2 id="a-halt-is-one-field-in-a-policy">A halt is one field in a policy</h2>

<p>A boolean would solve today’s problem and force a new format for tomorrow’s. I used a document whose fields are optional:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"halt"</span><span class="p">:</span><span class="w"> </span><span class="kc">true</span><span class="p">,</span><span class="w">
  </span><span class="nl">"direction_filter"</span><span class="p">:</span><span class="w"> </span><span class="kc">null</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>The current safety action is <code class="language-plaintext highlighter-rouge">halt</code>. Other fields can constrain future entries, but no remote field is allowed to increase configured risk.</p>

<p>Policies can exist at global, strategy, and instance scopes:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>control/policy.json
control/policy.&lt;strategy&gt;.json
control/policy.&lt;instance-label&gt;.json
</code></pre></div></div>

<p>Ordinary fields merge from broad to specific. <code class="language-plaintext highlighter-rouge">halt</code> is different: it is OR-ed across every layer. A narrower document cannot undo a global halt. To resume, every active halt must be cleared.</p>

<p>That asymmetry is deliberate. Safety-critical state should ratchet toward less activity, not be relaxed accidentally by a more specific override.</p>

<h2 id="remote-input-is-untrusted-input">Remote input is untrusted input</h2>

<p>A policy edited from a phone is easy to mistype. The resolver therefore:</p>

<ul>
  <li>accepts only known fields</li>
  <li>validates values before constructing the policy</li>
  <li>ignores an invalid document rather than applying half of it</li>
  <li>preserves the bot’s configured risk limits</li>
  <li>catches its own failures so it cannot crash the trading loop</li>
</ul>

<p>Remote reads are cached for a short interval. The local file is checked on every iteration so the offline brake remains immediate.</p>

<p>Fetch failure and “no policy exists” are separate states. Repeated remote failures raise an alert because the control path may be unavailable, but they do not invent a new policy.</p>

<h2 id="halt-means-flatten-then-confirm">Halt means flatten, then confirm</h2>

<p>My first version stopped new entries and allowed an open trade to reach its normal exit. That is a pause button, not an emergency stop.</p>

<p>The current behavior attempts to cancel the resting exit and market-close the position. The session ends only after the broker confirms the account is flat.</p>

<p>If the close cannot be confirmed, the bot does not simply exit. It continues managing the existing order path and raises urgent alerts. “I sent a close request” and “the position is closed” are different states.</p>

<p>Other policy changes affect future entries only. A direction filter should not mutate the terms of a trade already in progress.</p>

<h2 id="the-s3-missing-object-trap">The S3 missing-object trap</h2>

<p>The least-obvious failure came from IAM. With object-read permission but no bucket-list permission, S3 can return <code class="language-plaintext highlighter-rouge">403 AccessDenied</code> for a missing key rather than <code class="language-plaintext highlighter-rouge">404 Not Found</code>.</p>

<p>A missing scoped policy is normal. A <code class="language-plaintext highlighter-rouge">403</code> looks like a broken control channel and triggers false alarms.</p>

<p>The fix was to grant narrowly scoped bucket-list access for the control prefix in addition to object reads. Least privilege is still the goal, but the smallest-looking permission set is not correct if it changes normal absence into an error.</p>

<p>The final design has two brakes: a network-independent local halt and an outbound-only remote policy. Both share one invariant: the bot may stop only after it knows what happened to the position.</p>

<p><em>This is an educational systems-design example, not investment advice.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="reliability" /><category term="aws" /><summary type="html"><![CDATA[How a local halt file became a scoped S3 policy system that can flatten an autonomous trading bot without opening an inbound service to the bot.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">A Backtest Needs Two IDs</title><link href="https://luispe.me/2026/07/07/backtest-variants-versus-runs.html" rel="alternate" type="text/html" title="A Backtest Needs Two IDs" /><published>2026-07-07T00:00:00+00:00</published><updated>2026-07-07T00:00:00+00:00</updated><id>https://luispe.me/2026/07/07/backtest-variants-versus-runs</id><content type="html" xml:base="https://luispe.me/2026/07/07/backtest-variants-versus-runs.html"><![CDATA[<p>When a strategy has been backtested hundreds of times, “which run was that?” stops being an administrative question. It becomes part of the evidence.</p>

<p>My backtester already assigned a deterministic ID to every full configuration. Same inputs, same ID; change an input, get a different ID. Output files and crash-resume checkpoints were keyed to it.</p>

<p>That solved accidental overwrites. It also hid a modeling mistake: I was treating a strategy and one evaluation of that strategy as the same object.</p>

<h2 id="the-window-changed-the-identity-of-the-edge">The window changed the identity of the edge</h2>

<p>The fingerprint included everything, including the start and end dates. When I reran a promoted configuration on newer data, it received an unrelated ID. There was no durable link saying, “this is the same strategy definition measured in a different period.”</p>

<p>The comparison I cared about most was the one the data model could not express.</p>

<p>So I split one identity into two:</p>

<ul>
  <li>A <strong>variant</strong> is the strategy definition: entry logic and exit configuration.</li>
  <li>A <strong>run</strong> is one evaluation of that variant, including its data window, account-sizing assumption, and fill model.</li>
</ul>

<p>Re-evaluating the same edge on a new period keeps the variant ID and receives a new run ID.</p>

<h2 id="partition-the-configuration-once">Partition the configuration once</h2>

<p>The implementation starts with one canonical payload. Context keys are excluded only when producing the variant fingerprint:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">_CONTEXT_KEYS</span> <span class="o">=</span> <span class="nb">frozenset</span><span class="p">({</span>
    <span class="s">"file_path"</span><span class="p">,</span>
    <span class="s">"account_size"</span><span class="p">,</span>
    <span class="s">"start_date"</span><span class="p">,</span>
    <span class="s">"end_date"</span><span class="p">,</span>
    <span class="s">"tick_replay"</span><span class="p">,</span>
    <span class="s">"fill_pricing_mode"</span><span class="p">,</span>
    <span class="s">"exit_candles_path"</span><span class="p">,</span>
<span class="p">})</span>


<span class="k">def</span> <span class="nf">variant_payload</span><span class="p">(</span><span class="n">payload</span><span class="p">:</span> <span class="nb">dict</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">dict</span><span class="p">:</span>
    <span class="k">return</span> <span class="p">{</span><span class="n">key</span><span class="p">:</span> <span class="n">value</span> <span class="k">for</span> <span class="n">key</span><span class="p">,</span> <span class="n">value</span> <span class="ow">in</span> <span class="n">payload</span><span class="p">.</span><span class="n">items</span><span class="p">()</span>
            <span class="k">if</span> <span class="n">key</span> <span class="ow">not</span> <span class="ow">in</span> <span class="n">_CONTEXT_KEYS</span><span class="p">}</span>
</code></pre></div></div>

<p>Both IDs come from the same serialization and fingerprinting path. That is important: two parallel implementations would eventually disagree about a default or nested field.</p>

<p>Fill modeling belongs to run context. Switching from candles to tick replay can materially change measured results, but it does not create a new trading idea. It creates a more faithful evaluation of the same idea.</p>

<h2 id="preserve-old-run-ids-during-migration">Preserve old run IDs during migration</h2>

<p>Historical filenames and checkpoints already depended on the original full-configuration hash. I kept that hash byte-for-byte as the run fingerprint and added only the variant fingerprint.</p>

<p>The migration reconstructs every historical payload through the same production functions used for a new run, then backfills the variant columns. Afterward, a simple filter returns every evaluation of one edge across dates and fill assumptions.</p>

<p>The migration also exposed how much apparent experimentation was repeated measurement. Several historical runs collapsed into fewer distinct variants. That is useful information in itself.</p>

<h2 id="small-abstraction-quiet-bugs">Small abstraction, quiet bugs</h2>

<p>An independent review found that parameters for one strategy were being threaded into the fingerprint of unrelated strategies. Those unused values could fragment a variant even though they had no effect on behavior.</p>

<p>It also found a schema hazard: appending new fields to an unmigrated CSV could place values under the wrong headers. Both cases now fail loudly, and guard tests keep the migration’s defaults aligned with the live configuration.</p>

<p>The design lesson is broader than backtesting. When an object is evaluated repeatedly, the thing being evaluated and the conditions of one evaluation need separate identities.</p>

<p>Without that split, reproducibility tells you how to recreate a file. With it, you can also ask whether the same idea held up somewhere else.</p>

<p><em>This post covers backtest system design for educational purposes, not investment advice. Historical evaluations do not guarantee future results.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="backtesting" /><category term="data-modeling" /><category term="python" /><summary type="html"><![CDATA[Separating strategy variants from evaluation runs made my backtests easier to reproduce, compare across windows, and migrate safely over time.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Teaching My Backtester Which Trades Not to Take</title><link href="https://luispe.me/2026/06/30/instrumenting-backtest-signals-and-runs.html" rel="alternate" type="text/html" title="Teaching My Backtester Which Trades Not to Take" /><published>2026-06-30T00:00:00+00:00</published><updated>2026-06-30T00:00:00+00:00</updated><id>https://luispe.me/2026/06/30/instrumenting-backtest-signals-and-runs</id><content type="html" xml:base="https://luispe.me/2026/06/30/instrumenting-backtest-signals-and-runs.html"><![CDATA[<p>Aggregate backtest results tell me whether a strategy deserves another question. They rarely tell me which question to ask.</p>

<p>While reviewing losing trades in a 0DTE divergence strategy, two patterns kept bothering me. Some entries appeared to fight a nearby moving average. Others fired when the stochastic oscillator had only just qualified instead of reaching a deeper extreme.</p>

<p>Those were hypotheses, not filters. I wanted to test them without changing the entry logic.</p>

<h2 id="add-context-before-adding-rules">Add context before adding rules</h2>

<p>The signal detector already knew which bar qualified. I extended its output with the market state at that moment:</p>

<ul>
  <li>the oscillator value at the signal</li>
  <li>signed distance from price to several moving averages</li>
  <li>direction, so “near resistance” and “near support” are analyzed separately</li>
</ul>

<p>Each value is calculated once and written to the signals CSV. The strategy takes exactly the same trades as before.</p>

<p>An analysis script then joins signals to completed trades and reports linear and rank correlations alongside bucketed win rates. The first pass suggested that signals deeper in the oscillator’s extreme zone performed differently from those that barely qualified.</p>

<p>That is not enough evidence to promote a rule. It is enough to define the next experiment: test a threshold out of sample and compare the filtered variant against the unchanged baseline.</p>

<p>The distinction matters. Instrumentation produced a hypothesis; it did not prove an edge.</p>

<h2 id="the-bigger-failure-was-run-bookkeeping">The bigger failure was run bookkeeping</h2>

<p>While adding the new columns, I ran into a more basic trust problem. I had accumulated manual variant labels, handwritten commands, and output files whose configuration was not recoverable from the filename.</p>

<p>Worse, a forgotten label could let two configurations share a checkpoint. A restarted backtest might resume from signals generated under different parameters without saying so.</p>

<p>I replaced the label with a deterministic identity derived from the full configuration:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>canonical configuration
  → SHA-256 fingerprint
  → short collision-aware run ID
  → indexed outputs and checkpoints
</code></pre></div></div>

<p>The same configuration receives the same ID. Change anything that can affect the result and the ID changes. Each invocation is recorded with its configuration, output summary, and reproducible command.</p>

<p>This removed a human step and made accidental checkpoint reuse much harder.</p>

<h2 id="cold-review-found-the-quiet-bugs">Cold review found the quiet bugs</h2>

<p>An independent review of the diff found three gaps I had missed:</p>

<ol>
  <li>The list of hashed parameters could drift from the function signature.</li>
  <li>An exit path changed candle resolution based on which file existed, but that input was missing from the fingerprint.</li>
  <li>Resuming an older checkpoint could mix valid new feature values with missing ones.</li>
</ol>

<p>None changed the strategy logic. All could change what I believed about a result.</p>

<p>I added guard tests for parameter parity, included hidden data dependencies in the fingerprint, and made incompatible checkpoints fail visibly.</p>

<p>I also simplified the run index. Instead of expanding every strategy parameter into a growing set of CSV columns, each row stores one canonical JSON configuration. The index stays stable while individual strategies evolve.</p>

<h2 id="trust-is-a-backtest-feature">Trust is a backtest feature</h2>

<p>This work did not improve the reported performance of the strategy. It improved the chain of evidence:</p>

<ul>
  <li>the signal row preserves the context I want to study</li>
  <li>the trade row records the outcome</li>
  <li>the run index records how both were produced</li>
  <li>the identifier prevents unlike runs from sharing state</li>
</ul>

<p>That is less glamorous than a new entry rule. It is also what makes the next rule testable.</p>

<p><em>This is an educational account of backtest tooling, not investment advice. Historical results do not establish future performance.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="backtesting" /><category term="automated-trading" /><category term="python" /><summary type="html"><![CDATA[I added market context to every signal and deterministic run identities so I could test trade filters without changing strategy behavior at all.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">When My Backtest Changed Its Mind</title><link href="https://luispe.me/2026/06/30/replaying-0dte-option-fills-from-tick-data.html" rel="alternate" type="text/html" title="When My Backtest Changed Its Mind" /><published>2026-06-30T00:00:00+00:00</published><updated>2026-06-30T00:00:00+00:00</updated><id>https://luispe.me/2026/06/30/replaying-0dte-option-fills-from-tick-data</id><content type="html" xml:base="https://luispe.me/2026/06/30/replaying-0dte-option-fills-from-tick-data.html"><![CDATA[<p>My candle-based backtest liked a 0DTE options strategy. The live system did not.</p>

<p>On matched trades, the gap was too large to explain away as ordinary slippage. The backtest had turned a losing period into a winning one because it was answering two questions that minute candles cannot answer reliably:</p>

<ol>
  <li>Which exit condition happened first inside the bar?</li>
  <li>What price could the order actually receive?</li>
</ol>

<p>For a path-dependent exit such as a trailing stop, those are not details. They are the result.</p>

<h2 id="a-candle-has-no-sequence">A candle has no sequence</h2>

<p>Suppose one minute has both a low below the stop and a high above the next trailing level. OHLC records both extremes but not their order.</p>

<p>My engine resolved that ambiguity too favorably. It could register a new high, ratchet the trail, and book a profitable exit even when the live path had touched the stop first.</p>

<p>The candle model also filled at theoretical levels without observing the market’s actual prints. The combined bias was directional, not random, so optimizing trail width against it meant optimizing against a broken measuring instrument.</p>

<h2 id="replay-the-tape-in-order">Replay the tape, in order</h2>

<p>I rebuilt the exit simulation around timestamped option trades. For each historical position, the engine now:</p>

<ol>
  <li>loads the contract’s prints during the holding window</li>
  <li>sorts them in timestamp order</li>
  <li>updates the running high on every print</li>
  <li>applies stop, target, trail, and time rules in sequence</li>
  <li>lets the first satisfied condition win</li>
</ol>

<p>The candle engine remains available as a lower-fidelity baseline. Tick replay is opt-in so I can compare the two models on the same entries.</p>

<p>The result changed direction. The optimistic candle run became a losing tick-replay run and moved much closer to the observed live behavior. That did not prove the live strategy was sound. It showed that the previous backtest had overstated it.</p>

<h2 id="trades-delivered-more-value-than-missing-quotes">Trades delivered more value than missing quotes</h2>

<p>I expected NBBO quotes to be essential for realistic spread modeling. The data plan available to this experiment included trade prints but not the historical quote endpoint.</p>

<p>That limitation forced a useful test: were ordered prints enough to remove the dominant bias?</p>

<p>On the matched panel, they were. The residual difference between tick replay and live fills was small relative to the correction from intrabar ordering. Prints also contain some realized spread information: the trade that triggers a sell stop often occurs near the bid rather than at a frictionless theoretical level.</p>

<p>This is a conclusion about this sample, not a universal claim that quotes do not matter.</p>

<h2 id="i-deleted-the-correction-that-looked-more-realistic">I deleted the correction that looked more realistic</h2>

<p>I briefly tested a synthetic spread calibrated from a limited month of quote captures. Applying a flat half-spread made one comparison look better.</p>

<p>It was also the wrong model:</p>

<ul>
  <li>trade prints already embedded some spread, so the adjustment double-counted it</li>
  <li>a flat value ignored volatility, time of day, liquidity, and time to expiry</li>
  <li>the calibration could not be validated in periods without quotes</li>
</ul>

<p>A visible limitation was preferable to an untestable correction tuned to one window. Real quotes can support a quote-based fill mode later; a constant chosen because it improves a chart should not quietly become historical truth.</p>

<h2 id="instrument-the-instrument">Instrument the instrument</h2>

<p>Tick data has its own failure mode: sparse prints. Each replayed trade now records the number of prints in its actual holding window and a simple fill-quality status:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ok | sparse | no_trades
</code></pre></div></div>

<p>That flag does not repair thin data. It prevents the engine from presenting a low-confidence path as equally trustworthy.</p>

<p>The review caught two important implementation errors before the change landed: a timestamp fallback that could misread epoch units, and a quality metric that counted the broader scan window instead of the position’s hold window. The full test suite now covers both.</p>

<p>The strategy still has to earn confidence through new evidence. But the backtest now distinguishes what it observed, what it inferred, and where the tape was too thin to know.</p>

<p><em>This is an educational backtesting case study, not investment advice. Tick replay and historical results do not predict future profitability.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="backtesting" /><category term="market-data" /><category term="python" /><summary type="html"><![CDATA[Replaying ordered option trades reversed an optimistic 0DTE backtest and exposed why candle fills fail for path-dependent exits in live comparisons.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">The Trail Wasn’t the Only Problem</title><link href="https://luispe.me/2026/06/29/why-my-trailing-stop-backtest-misled-me.html" rel="alternate" type="text/html" title="The Trail Wasn’t the Only Problem" /><published>2026-06-29T00:00:00+00:00</published><updated>2026-06-29T00:00:00+00:00</updated><id>https://luispe.me/2026/06/29/why-my-trailing-stop-backtest-misled-me</id><content type="html" xml:base="https://luispe.me/2026/06/29/why-my-trailing-stop-backtest-misled-me.html"><![CDATA[<p>I started with a narrow question: was my trailing stop too tight for a fast-moving 0DTE option?</p>

<p>In live runs, the trail sometimes triggered faster than my polling loop could explain. So I recorded the option’s tick-by-tick path and measured pullbacks that recovered before the next high.</p>

<p>The first result was useful: nearly half of the recovered pullbacks in the sample were deeper than the live trail. The stop was sitting inside ordinary movement for those trades.</p>

<p>But “make it wider” was not a complete answer.</p>

<h2 id="typical-trades-and-rare-runners-wanted-different-things">Typical trades and rare runners wanted different things</h2>

<p>When I replayed several trail widths, the median trade favored a tighter exit. Total return favored a wider one because a few large moves dominated the aggregate.</p>

<p>That is a product decision disguised as a parameter choice:</p>

<ul>
  <li>optimize the common trade and cut give-back</li>
  <li>or tolerate more give-back to remain exposed to rare runners</li>
</ul>

<p>A single fixed trail cannot maximize both objectives. Before changing live behavior, I needed to know whether I could identify the regime early enough.</p>

<h2 id="the-smarter-gates-arrived-too-late">The smarter gates arrived too late</h2>

<p>I tested several prototypes: option-path confirmation, entry-time volatility and trend filters, and early follow-through in the underlying.</p>

<p>None improved on a simple fixed trail in this small sample.</p>

<p>The entry-time features did not separate the regimes. The feature that did show promise—whether the underlying continued in the trade’s direction—resolved too slowly. By the time the signal became informative, the option had often completed the move I wanted the trail to manage.</p>

<p>The underlying was explaining the regime on a minutes-long clock. The option was repricing on a seconds-long clock.</p>

<p>That mismatch is easy to miss when every observation ends up in the same spreadsheet row.</p>

<h2 id="then-the-validators-disagreed">Then the validators disagreed</h2>

<p>I compared matched trades across three sources:</p>

<table>
  <thead>
    <tr>
      <th>Source</th>
      <th>What it represented</th>
      <th>Directional result</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Candle backtest</td>
      <td>Simulated historical exits</td>
      <td>Strongly positive</td>
    </tr>
    <tr>
      <td>Paper experiment</td>
      <td>Forward test with simulated fills</td>
      <td>Negative</td>
    </tr>
    <tr>
      <td>Live behavior</td>
      <td>Actual broker orders and fills</td>
      <td>Negative</td>
    </tr>
  </tbody>
</table>

<p>The gap was too large to call slippage. The backtest and the live system were measuring different paths.</p>

<p>My initial hypothesis focused on spread and fill assumptions. That was plausible, but not yet proved. Minute candles also hid the order of events inside each bar, which is decisive for a trailing stop: did the option hit the stop first, or make a new high first?</p>

<p>I left the live parameter unchanged and treated the wider trail as a paper experiment. More importantly, I stopped treating the candle backtest’s absolute result as evidence until I could replay the actual sequence of prints.</p>

<p>That next test changed the diagnosis. <a href="/2026/06/30/replaying-0dte-option-fills-from-tick-data.html">The follow-up rebuilds fills from ordered tick data</a> and separates the largest source of bias from the costs I had only inferred here.</p>

<h2 id="what-i-kept">What I kept</h2>

<p>Three lessons survived the revision:</p>

<ol>
  <li>Measure the path, not only the outcome. Path-dependent exits need path-level data.</li>
  <li>Do not out-clever a small sample. A more adaptive rule is not automatically a better one.</li>
  <li>Validate the validator. Backtest, paper, and live results are different evidence and should stay labeled that way.</li>
</ol>

<p>This was one month and a few dozen matched trades. The findings were provisional—but provisional and measured was still better than confident and guessed.</p>

<p><em>This experiment is educational and is not investment advice. Backtests and paper results do not establish future profitability.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="backtesting" /><category term="market-data" /><summary type="html"><![CDATA[A 0DTE trailing-stop experiment became a lesson in small samples, path-dependent exits, and validating the tools used to validate a strategy.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">From Disk to S3: A Safer Trade-Journal Pipeline</title><link href="https://luispe.me/2026/06/28/moving-trading-journals-from-disk-to-s3.html" rel="alternate" type="text/html" title="From Disk to S3: A Safer Trade-Journal Pipeline" /><published>2026-06-28T00:00:00+00:00</published><updated>2026-06-28T00:00:00+00:00</updated><id>https://luispe.me/2026/06/28/moving-trading-journals-from-disk-to-s3</id><content type="html" xml:base="https://luispe.me/2026/06/28/moving-trading-journals-from-disk-to-s3.html"><![CDATA[<p>Every completed trade in my bot becomes a row in a CSV journal. For a long time, those files lived on the trading machine and were copied through Git as an informal backup.</p>

<p>That was enough until I wanted the data available for analysis. The useful change was not simply “upload CSVs to S3.” It was deciding which failure should be allowed to affect which part of the system.</p>

<h2 id="local-persistence-remains-the-source-of-truth">Local persistence remains the source of truth</h2>

<p>After a journal row is written successfully, the bot calls a small S3 upload helper. The destination bucket comes from an environment variable, and the upload is a no-op when cloud sync is not configured.</p>

<p>The sequence matters:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>close trade
  → append journal row locally
  → confirm local write
  → attempt cloud sync
  → warn, but preserve the row, if sync fails
</code></pre></div></div>

<p>The upload sits outside the local write’s exception handler. Otherwise, an S3 outage could produce a “journal write failed” error even though the row was safely on disk. That message would be both alarming and wrong.</p>

<p>Local durability and remote availability are separate outcomes, so the code reports them separately.</p>

<p>The S3 client is initialized lazily and reused by the long-running process. The object key also separates raw inputs from future analytics outputs:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>landing/journals/&lt;year&gt;/&lt;filename&gt;
</code></pre></div></div>

<p>The bot writes only to the landing prefix. An analytics job can read from there and write curated tables elsewhere under a different role. The boundary keeps permissions and ownership understandable.</p>

<h2 id="historical-data-was-the-harder-part">Historical data was the harder part</h2>

<p>New uploads solved only the next trade. The existing archive contained several journal schemas from different stages of the bot:</p>

<ul>
  <li>an early, smaller schema with one symbol and one entry price</li>
  <li>a transitional options schema</li>
  <li>the current account-scoped schema with separate underlying and option fields</li>
</ul>

<p>I built the migration around the data that actually existed, not the schema I wished had existed. It detects the source shape, maps fields conservatively, calculates only derivable values, and leaves unavailable fields empty.</p>

<p>The natural deduplication key combines strategy, entry time, and contract. Existing annual rows win over imported archive rows. The migration writes backups before modifying an annual journal and produces the same result when run again.</p>

<p>That idempotence matters because migrations rarely happen once. They get interrupted, reviewed, rerun, and occasionally resumed months later by someone who has forgotten the original assumptions.</p>

<h2 id="git-was-not-the-first-thing-to-remove">Git was not the first thing to remove</h2>

<p>Once S3 existed, removing journals from Git looked obvious. Operationally, it was premature.</p>

<p>When a tracked file is deleted in a commit, another machine that pulls the change also deletes its local copy. That is correct Git behavior and a poor surprise for a stateful production host.</p>

<p>So I kept the existing backup path until the S3 flow was validated end to end. The sequence is now:</p>

<ol>
  <li>Upload new rows reliably.</li>
  <li>Reconcile local journals against S3.</li>
  <li>Test restoration.</li>
  <li>Only then remove the files from version control in a coordinated change.</li>
</ol>

<p>The takeaway is not that object storage is complicated. It is that adding a new durable path does not make the old one disposable on day one.</p>

<p>Design the handoff for partial success: a trade journal can be safe locally even when cloud sync is down, and a migration can stop halfway without destroying the history it is trying to preserve.</p>

<p><em>This post describes system design, not investment advice.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="data-engineering" /><category term="aws" /><summary type="html"><![CDATA[A practical design for syncing trading journals to S3 without turning a cloud outage during sync into a false local-write failure or lost history.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">One Strategy, Two Accounts, Zero Silent Fallbacks</title><link href="https://luispe.me/2026/06/20/running-one-strategy-across-multiple-accounts.html" rel="alternate" type="text/html" title="One Strategy, Two Accounts, Zero Silent Fallbacks" /><published>2026-06-20T00:00:00+00:00</published><updated>2026-06-20T00:00:00+00:00</updated><id>https://luispe.me/2026/06/20/running-one-strategy-across-multiple-accounts</id><content type="html" xml:base="https://luispe.me/2026/06/20/running-one-strategy-across-multiple-accounts.html"><![CDATA[<p>Running one strategy against two brokerage accounts sounds like a configuration change. In a live trading system, it is an isolation problem.</p>

<p>My bot originally assumed one process, one account, and one trade journal. Launching it twice would have sent both processes into the same CSV ledger. Positions, P&amp;L, and recovery state could be mixed before I noticed anything was wrong.</p>

<p>The feature was not “run the bot twice.” It was “make every side effect belong to exactly one account.”</p>

<h2 id="give-each-process-an-identity">Give each process an identity</h2>

<p>Each bot instance now receives an explicit account selection and derives a non-secret label for operational output. That label scopes three things:</p>

<ul>
  <li>its trade journal</li>
  <li>its log file</li>
  <li>every notification it sends</li>
</ul>

<p>The filenames follow a pattern like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>2026_perma_journal_&lt;account-label&gt;.csv
permabot_&lt;account-label&gt;.log
</code></pre></div></div>

<p>Separate journals also mean separate file locks. One process cannot block or corrupt another account’s write, and cumulative results are calculated from the correct history.</p>

<p>The label is useful for observability, but it is not authorization. Credentials stay in environment variables, and neither the label nor a real account identifier belongs in source control or public logs.</p>

<h2 id="fail-loudly-when-identity-is-missing">Fail loudly when identity is missing</h2>

<p>The most important behavior is what the bot refuses to do.</p>

<p>If an operator selects an account whose credentials are not configured, startup fails. It does not fall back to the primary account. A silent fallback could place the intended trades twice in one account while leaving the other untouched.</p>

<p>For software that can move money, an explicit failure is safer than a plausible guess.</p>

<p>I applied the same rule to alerts. My first implementation added the account label inside the notification helper. It worked, but the text at each call site no longer matched the message that was actually sent. I moved the label into the call sites so the source shows the complete alert.</p>

<p>That is a small readability choice until something breaks near the close. Then “what you read is what gets sent” becomes an operational feature.</p>

<h2 id="migrate-history-without-gambling-on-it">Migrate history without gambling on it</h2>

<p>Changing the journal convention created a data migration. Existing files had to move to account-scoped names without losing prior trades or overwriting a newer target.</p>

<p>I used a small idempotent migration:</p>

<ol>
  <li>Resolve the old and new paths.</li>
  <li>Stop if the target already exists.</li>
  <li>Preserve the original until the move succeeds.</li>
  <li>Make a second run a no-op.</li>
</ol>

<p>“Solo project” does not make historical state disposable. If a system resumes from files, renaming those files is a production change.</p>

<h2 id="isolation-revealed-the-next-shared-dependency">Isolation revealed the next shared dependency</h2>

<p>The account-level files are now independent, but the processes still depend on shared brokerage authentication state. A token refresh in one process can invalidate the in-memory token held by another.</p>

<p>That is the next boundary to fix: one component should own refresh, while the workers adopt the latest valid token instead of racing to rotate it.</p>

<p>The broader lesson is simple. Multi-account support is not duplication. It is identity carried consistently through configuration, persistence, observability, and failure behavior.</p>

<p>When software trades unattended, “it runs twice” and “the two runs cannot confuse each other” are very different standards.</p>

<p><em>This is an engineering case study for educational purposes, not investment advice.</em></p>]]></content><author><name>Luis P. Perez</name></author><category term="automated-trading" /><category term="reliability" /><category term="python" /><summary type="html"><![CDATA[How I isolated journals, logs, credentials, and alerts before letting one automated trading strategy run safely across multiple brokerage accounts.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Ticket Hierarchy in JIRA</title><link href="https://luispe.me/2025/02/08/ticket-hierarchy-in-jira.html" rel="alternate" type="text/html" title="Ticket Hierarchy in JIRA" /><published>2025-02-08T00:00:00+00:00</published><updated>2025-02-08T00:00:00+00:00</updated><id>https://luispe.me/2025/02/08/ticket-hierarchy-in-jira</id><content type="html" xml:base="https://luispe.me/2025/02/08/ticket-hierarchy-in-jira.html"><![CDATA[<h2 id="defining-ticket-hierarchy-in-jira">Defining Ticket Hierarchy in JIRA</h2>

<p>In any software project, maintaining a <strong>clear ticket hierarchy</strong> is essential for organizing work, ensuring accountability, and driving efficient development. In this post, I’ll break down the different ticket types used in <strong>JIRA</strong> and how I structure them for my <strong>Permabot project</strong>.</p>

<h2 id="understanding-jira-ticket-types"><strong>Understanding JIRA Ticket Types</strong></h2>

<p>JIRA provides several ticket types, each serving a specific purpose. Here’s how I categorize them:</p>

<ul>
  <li><strong>Epic</strong> – A high-level deliverable representing a scoped user value.</li>
  <li><strong>Story (User Story)</strong> – A feature or user interaction that enhances the product.</li>
  <li><strong>Bug</strong> – An unintended behavior that needs fixing.</li>
  <li><strong>Task</strong> – Non-development work, such as data backfilling or customer interactions.</li>
  <li><strong>Subtask</strong> – The smallest unit of work, breaking down a Story, Bug, or Task.</li>
</ul>

<p>A well-structured hierarchy ensures <strong>clarity in ownership, progress tracking, and smooth execution</strong>.</p>

<hr />

<h2 id="example-permabots-ticket-hierarchy"><strong>Example: Permabot’s Ticket Hierarchy</strong></h2>

<p>Here’s how I structure JIRA tickets for <strong>Permabot</strong>:</p>

<ol>
  <li><strong>Epic:</strong> Clearly defines end-user value and deliverables.</li>
  <li><strong>Stories:</strong> Break down the epic into actionable work.</li>
  <li><strong>Bugs:</strong> Track issues that arise during testing.</li>
</ol>

<h3 id="jira-ticket-breakdown-example"><strong>JIRA Ticket Breakdown Example</strong></h3>

<p>For Permabot v2.3.1, the Epic started with these high-level goals:</p>

<ul>
  <li>Improve logging to capture delta values for option legs, enabling better risk assessment and strategy adjustments.</li>
  <li>Implement dynamic contract sizing to limit potential losses to a maximum of 3% per trade on a $21,000 account.</li>
  <li>Enhance logging for HTTP errors to improve debugging and system reliability.</li>
</ul>

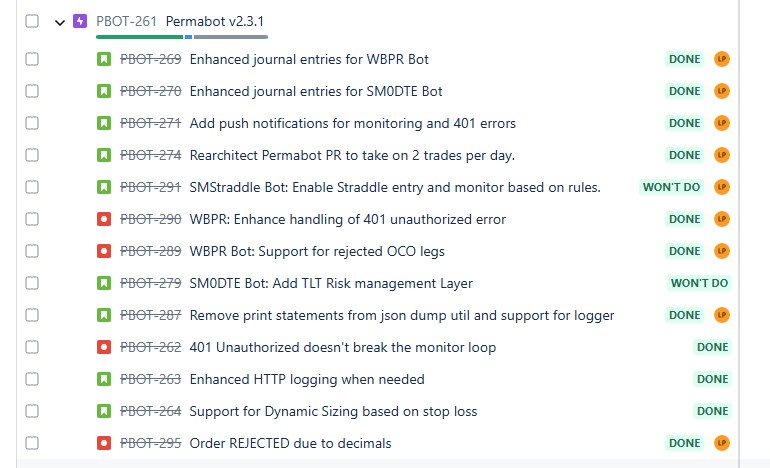
<p>Here’s how my JIRA hierarchy appears in the timeline view:</p>

<p><img src="/assets/images/jira-timeline-permabot-v2.3.1-done.jpg" alt="JIRA Ticket Hierarchy" /></p>

<p>During development, the number of features expanded due to <strong>scope creep</strong>. While this is natural, as deeper exploration surfaces additional issues and opportunities, it’s crucial for a <strong>product manager to monitor and manage scope effectively</strong>. As a general rule, I allow developers to add necessary stories when changes to existing code are required to deliver on the original goals. For instance, before enhancing HTTP error logging, it may be necessary to implement basic logging first. However, external stakeholders should not bypass the product manager when requesting additional features directly from developers.</p>

<p>Another key takeaway is that the Epic initially had <strong>zero bugs</strong>, but as development progressed, unexpected behaviors surfaced—especially given that <strong>the software is still evolving</strong> despite being at version v2.3+. This is normal. Logging these issues ensures they are addressed appropriately, whether as immediate fixes (<strong>P0 priority</strong>) or for future consideration (<strong>P1+ priority</strong>). I’ll cover prioritization strategies in a separate post.</p>

<hr />

<h2 id="example-changelog-permabot-v231"><strong>Example Changelog: Permabot v2.3.1</strong></h2>

<p>Here’s a real changelog from one of Permabot’s releases:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>## [2.3.1] - 2024-XX
### Added
- Configured max delta to 0.20 and stop loss is 1.75x
- Created Utils function to log response / requests for debugging
- Dynamic sizing defaulting to 3% max loss on 21000 act
- Added push notifications for active monitoring, alerting in event of 401
- WBPR Bot: Refactored William's Brown Price Reversion strategy supporting &gt;1 daily entries
- Introduction of Perma Journal
- WBPR Bot: standardized notifications
- Json dump utils with logger support

### Fixed
- monitor_and_exit loop continues forever when there are http errors, in case connection comes back.
- WBPR Bot: no trade days end the bot
</code></pre></div></div>

<hr />

<h2 id="final-thoughts"><strong>Final Thoughts</strong></h2>
<p>A well-defined <strong>ticket hierarchy</strong> in JIRA helps ensure a structured and scalable software development process. By clearly defining <strong>Epics, Stories, Bugs, and Tasks</strong>, teams can streamline execution and maintain better control over project progress.</p>

<p><strong>How do you structure your JIRA tickets? Let’s connect and share insights!</strong></p>]]></content><author><name>Luis P. Perez</name></author><category term="product-management" /><category term="agile" /><summary type="html"><![CDATA[How I organize epics, stories, bugs, tasks, and subtasks to keep product development clear and adaptable.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://luispe.me/assets/images/og-card.png" /><media:content medium="image" url="https://luispe.me/assets/images/og-card.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>